


The Weight of Progress: How PrismML is Redefining the Physics of Artificial Intelligence

In the high-stakes race to build the world’s most capable artificial intelligence, the prevailing wisdom has long been that "bigger is better." For years, the industry has operated under the assumption that to achieve true reasoning capabilities, a model must be gargantuan, requiring massive server farms and cloud-scale infrastructure to function.
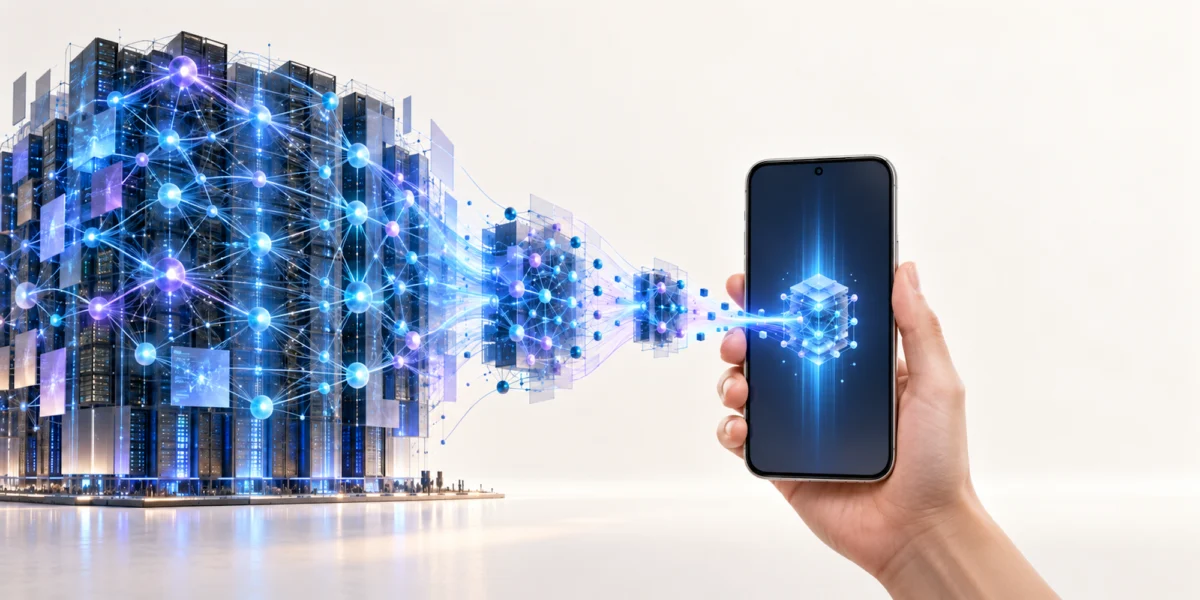
PrismML, a rising AI lab founded by researchers from the California Institute of Technology (Caltech), is betting that this fundamental assumption is wrong. The startup is not seeking to build the next trillion-parameter behemoth; instead, it is perfecting the art of "model compression," shrinking high-performing reasoning models until they are compact enough to reside comfortably on the smartphones and PCs already in the pockets and offices of millions.
While the startup has only secured a $22.25 million seed round—a modest sum in an era of multi-billion-dollar AI capital raises—it has captured the attention of the industry’s elite. With a pedigree rooted in academic excellence and backed by industry heavyweights, PrismML is positioning itself to shift the AI paradigm from cloud-dependent processing to local, on-device intelligence.
The Core Innovation: Ternary Compression
At the heart of PrismML’s value proposition is a technical breakthrough in how models store information. Large Language Models (LLMs) function based on "weights"—numerical values that the model learns during training, which dictate how it processes information. Traditionally, each weight requires 16 bits of memory.
PrismML’s proprietary approach, termed "ternary weights," simplifies these values to just three states: +1, -1, or 0. By reducing the complexity of these weights, the startup can shrink a model’s footprint by a factor of 9x to 10x without sacrificing the underlying "intelligence" of the system.
This is not merely a theoretical exercise. On Thursday, the company released Bonsai 2 27B, a compressed version of Alibaba’s Qwen3.8 27B model. While the original model requires significant hardware resources, the PrismML version is optimized down to just 5.9 GB. This level of compression marks a new threshold for local AI, enabling advanced reasoning on consumer-grade hardware.
A Pedigree of Academic and Industrial Excellence
PrismML is the brainchild of Babak Hassibi, a professor at Caltech and a recognized authority in compression and signal processing. His academic background provides the theoretical bedrock for the startup’s success, but the company’s strategic direction is bolstered by a network of high-profile advisors.
Among them is Ion Stoica, a co-founder of data powerhouse Databricks and director of the Berkeley Sky Computing Lab. Stoica’s involvement is a significant indicator of the company’s potential; his lab has been the launchpad for several transformative AI ventures, including Letta and the SGLang project.
The startup’s cap table is similarly impressive, featuring backing from Khosla Ventures, Cerberus Capital, and Caltech itself. This mix of institutional investment and academic mentorship provides PrismML with the stability needed to pursue long-term technical research rather than chasing short-term, compute-heavy benchmarks.
Chronology of the "Bonsai" Revolution
The evolution of the Bonsai model family has been rapid, reflecting the startup’s iterative development process:
- March 2026: PrismML releases the first iteration of the Bonsai model. It achieves 95% performance parity with its base model but immediately finds a massive user base, garnering over 11 million downloads.
- Spring 2026: The startup sees an additional 2.6 million downloads of its smaller, specialized models, signaling a strong market demand for efficient, locally executable AI.
- July 2026: Reports emerge of potential discussions between PrismML and Apple regarding integration into the iPhone ecosystem. While CEO Babak Hassibi declined to comment, the speculation highlights the industry’s urgent need for on-device, low-latency AI solutions.
- August 2026: The official launch of Bonsai 2 27B. This release demonstrates a significant leap in efficiency, matching 98% of the original Qwen model’s benchmark scores—a marked improvement over the 95% threshold achieved just months prior.
Supporting Data: Efficiency vs. Accuracy
Critics of compression technology have long argued that shrinking a model inevitably leads to "intelligence decay." However, PrismML’s performance metrics suggest that the gap between compressed and full-sized models is narrowing at an exponential rate.
According to the company, Bonsai 2 maintains 98% of the aggregate benchmark scores of the uncompressed Qwen 27B. While Hassibi admits that "perfect" 100% parity remains a challenge due to the inherent nature of compression, he argues that the distinction is largely academic.
"LLMs are not so accurate in their uncompressed form, and benchmarks are not so perfectly reflective of actual tasks, that a 2% degradation would meaningfully affect how a model performs in actual use," Hassibi noted.
Furthermore, the company emphasizes that the "harness"—the software environment in which the model operates—is often more critical to the final user experience than the raw model size. By focusing on optimization, PrismML is ensuring that the models are not only small but also highly compatible with the software stacks already used by developers and hardware manufacturers.
Official Responses and Strategic Vision
The potential implications of PrismML’s technology go far beyond memory savings. As Ion Stoica noted in recent comments, the goal is to democratize intelligence.
"You are going to have intelligence at your fingertips," Stoica explained. "It’s going to be free because it’s going to run on the device you already bought. It’s also going to be private, because you’re not going to send your data to the cloud."
This emphasis on privacy and local execution addresses the primary friction point for enterprises and consumers alike: the fear of sending sensitive data to external servers. By decoupling intelligence from the cloud, PrismML is essentially turning every smartphone into an offline, autonomous reasoning agent.
Looking forward, the company has set an ambitious goal: applying its ternary compression technique to massive, multi-hundred-billion-parameter models.
"The next models that we will release, hopefully in the next couple of months, will be in the several-hundred-billion-parameter range," Hassibi stated. "I expect it will be easier to retain the intelligence there. As model size grows, there is more room to be able to compress them without losing the intelligence."
Implications: The Shift Toward Edge AI
If PrismML succeeds in its mission, the AI industry may be entering an "Edge AI" era. The implications are profound for several sectors:
1. Consumer Electronics
If a device as ubiquitous as an iPhone can run a high-reasoning, 27-billion-parameter model locally, the reliance on server-side APIs will plummet. This could force a restructuring of how companies like Apple, Google, and Samsung monetize AI services, moving away from subscription-heavy cloud models toward hardware-as-a-service or local feature differentiation.
2. Data Sovereignty and Privacy
For industries like healthcare, legal, and government, the ability to run sophisticated AI without transmitting data to a third-party server is a "holy grail." PrismML’s compression could become the standard for secure, offline AI deployments, allowing sensitive analysis to happen entirely within the secure boundary of a client’s hardware.
3. Sustainability and Compute Costs
The current trajectory of AI development is environmentally and financially unsustainable, with the energy consumption of massive data centers becoming a point of global concern. By enabling models to run on existing consumer hardware, PrismML offers a path toward a more sustainable AI ecosystem that leverages distributed, idle compute power rather than centralized, high-cost server clusters.
4. Developer Democratization
By lowering the barrier to entry for running high-reasoning models, PrismML is empowering individual developers and startups to build sophisticated applications that were previously the sole domain of Big Tech. If a single developer can run a powerful model on a laptop, the pace of innovation for small, specialized AI agents is likely to accelerate dramatically.
Conclusion: The "Small" Future
PrismML represents a contrarian but highly logical movement within the AI field. By focusing on the physics of model weights rather than the brute force of massive training clusters, the company is solving the most pressing challenges of the current AI boom: privacy, cost, and accessibility.
Whether or not the rumored partnerships with giants like Apple materialize, the technical trajectory of the company is clear. We are moving toward a future where intelligence is no longer an external service that we "dial into," but a local, persistent, and private utility integrated into the very fabric of our devices.
As PrismML turns its focus toward even larger models, the industry will be watching closely. If they can indeed prove that massive intelligence can be compressed without loss, they won’t just be a successful startup—they will have rewritten the rules for how the world consumes artificial intelligence. For a company that has raised just over $22 million, the impact of their "small" models is proving to be, in every sense, gargantuan.